We turn a text-to-video model into a fast, causal video-to-video model that stays consistent over long durations.
01 Problem
OverviewAutoregressive distillation methods [1, 2, 3] make video diffusion models fast and streaming, but their causal attention covers only a context window of recent frames. Once earlier content leaves the window, the model cannot condition on it, and revisited regions are generated inconsistently.
Baseline output (context window only)
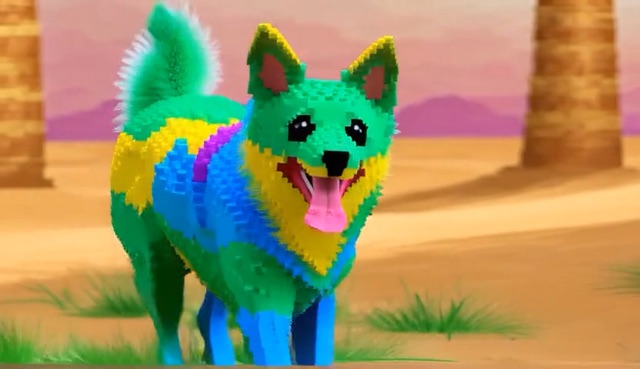
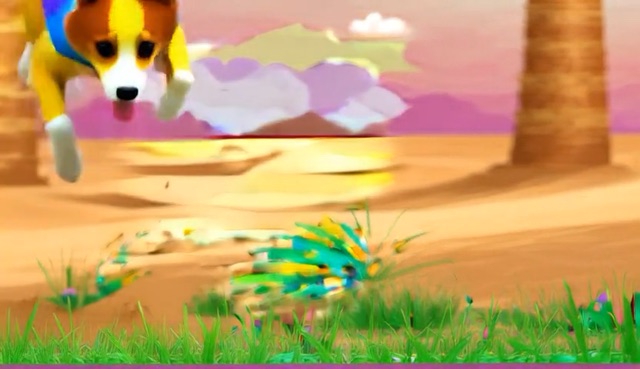
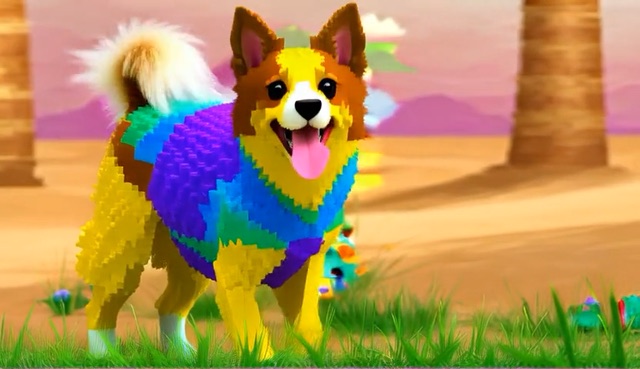
[1] Self-Forcing, Huang et al. 2025 [2] LongLive, Yang et al. 2025 [3] Rolling Forcing, Liu et al. 2025
02 Main insight
OverviewUnlike text-to-video generation, video-to-video translation has an input video. Patches that correspond across input frames tell the model which earlier outputs to reuse, even far outside the context window.
Input video
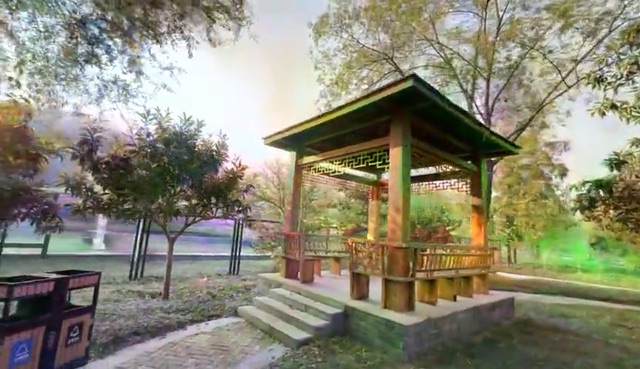
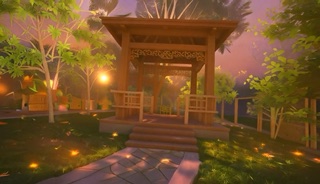
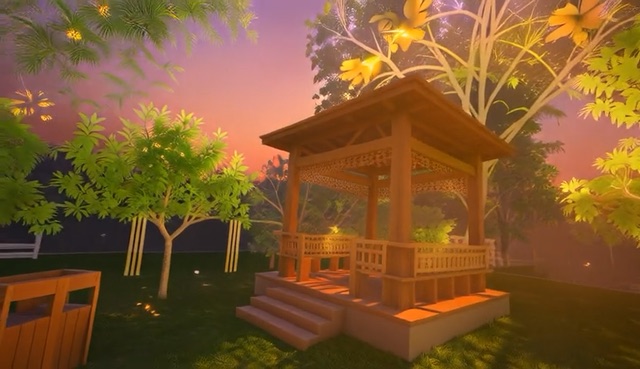
Output video
03 Method
OverviewWe keep a compressed history of input-output patch pairs. For each new block, every input patch retrieves the outputs of its nearest stored inputs, and a correspondence cross-attention layer conditions the model on them.
Let's consider the input at t = 0:53.
We maintain a history bank of unique key-value pairs from the past.
Input is patchified and flattened.
For each input query, we find the closest K matches* in the history bank.
We retrieve its value.
The model conditions on the retrieved patches to generate the output.
New key-value pairs are added to the history bank, only if they are unique.
* K = 1 for illustration.
04 Results
OverviewOur evaluation targets long-range consistency: we construct videos in which scenes repeat, and report the reconstruction error at each revisit. We apply our method to three different distillation methods: Self-Forcing [1], LongLive [2], and Rolling Forcing [3]. Our correspondence mechanism consistently improves long-context reconstruction across all three. The base model used is VACE 1.3B.
Long-context reconstruction error LPIPS, lower is better
Without correspondenceWith correspondence
VACE-Bench
DL3DV
| Benchmark | Distillation method | Without correspondence | With correspondence | Change |
|---|---|---|---|---|
| VACE-Bench | Self-Forcing | 0.548 | 0.343 | −37% |
| VACE-Bench | LongLive | 0.511 | 0.272 | −47% |
| VACE-Bench | Rolling Forcing | 0.427 | 0.240 | −44% |
| DL3DV | Self-Forcing | 0.616 | 0.451 | −27% |
| DL3DV | LongLive | 0.534 | 0.345 | −35% |
| DL3DV | Rolling Forcing | 0.445 | 0.305 | −32% |
Below, we show a gallery of results generated with our method.