Unit 4
Data Analysis 1
Conceptual and code reading questions
[23.1]
Match the term to its definition.
| Term | Definition |
|---|---|
| Categorical Data | Data falls into separate categories, but those categories can be compared in a specific order. |
| Ordinal Data | Data are numbers, mathematical operations can be performed on the data and it can be compared to other data. |
| Numerical Data | Data falls into one of many categories. Those categories are separate and cannot be compared. |
[23.2]
Identify the data type of each of the following examples.
| Question | Categorical | Ordinal | Numerical |
|---|---|---|---|
| Favorite Movie | |||
| Restaurant Rating | |||
| Test Score | |||
| Education Level | |||
| Height | |||
| Customer Satisfaction | |||
| Eye Color | |||
| Weight | |||
| Type of Pet |
[23.3]
Briefly explain the difference between ordinal data and numerical data.
[23.4]
Identify whether the following statements are true or false.
| Statement | True | False |
|---|---|---|
| CSV files store data that is nested, like trees. | ||
| CSV files store data in rows and columns. | ||
| JSON files can represent nested data structures. | ||
| A spreadsheet is an example of structured data | ||
| Each row in a CSV file represents one record | ||
| A plaintext file cannot store numbers |
[23.5]
Which statement best explains why CSV files can be described as "two-dimensional"?
- a. They only store two types of data
- b. They represent data using rows and columns
- c. They always contain two variables
- d. They can only be read using spreadsheet software
[23.6]
Match the term to its definition.
| Term | Definition |
|---|---|
| Slicing | Used to break up data that is separated by a known delimiter |
| Split | Used to remove parts of the data that are unnecessary. |
| Index | Used to remove whitespace (spaces, tabs, and newlines) from the front and back of a string |
| Strip | Used to find the location of the beginning or end of a section |
[23.7]
If s = “I like ice cream”, what is the result of s.split()?
a. [“I like ice cream”]
b. [“Ilikeicecream”]
c. [“I”, “like”, “ice”, “cream”]
d. [“I like”, “ice cream”]
[23.8]
If s = “computer”, what is the result of s[1:4]?
a. “comp”
b. “put”
c. “omp”
d. “Uter”
[23.9]
If s = “banana”, what is the result of s.index(“a”)?
a. 0
b. 1
c. 2
d. 3
e. 4
[23.10]
If s = “I like ice cream”, what is the result of s.strip()?
a. [“Ilikeicecream”]
b. “Ilikeicecream”
c. “I I like like ice ice cream cream”
d. “I like ice cream“
Code Writing questions
[23.11]
Assume we have the following list, lst = [“apple”, “orange”, “Banana”, “STRAWberry”, “grapE”, “raspberry”]. Write some lines of code to change each word in the list to be all caps.
[23.12]
Assume we have the following list, lst = [“apple”, “orange”, “Banana”, “STRAWberry”, “grapE”, “raspberry”]. Write some code such that all the words in the list have the first letter capitalized and the rest of the letters in lowercase.
[23.13]
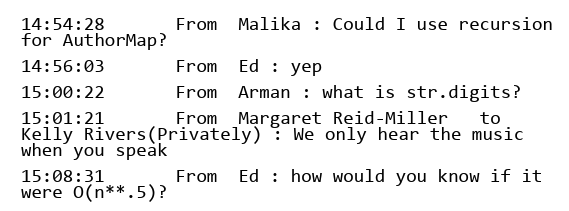
The code below is from lecture, where we were parsing a chat log. Assume each message occurs on an individual line.
# example code
f = open("chat.txt", "r")
text = f.read()
f.close()

people = [ ]
for line in text.split("\n"):
    start = line.index("From") + \ len("From")
    line = line[start:]
    end = line.index(" : ")
    line = line[:end]
    line = line.strip()
    people.append(line)
    print(people)
Using the code above as an example, write your own code to count the number of times the name Clare appears in the chat log.
[23.14]
The code below is from lecture, where we were parsing a chat log. Assume each message occurs on an individual line.
# example code
f = open("chat.txt", "r")
text = f.read()
f.close()

people = [ ]
for line in text.split("\n"):
    start = line.index("From") + \ len("From")
    line = line[start:]
    end = line.index(" : ")
    line = line[:end]
    line = line.strip()
    people.append(line)
    print(people)
Using the code above as an example, write your own code to find who sent a message to Professor Rivers .
[23.15]
The code below is from lecture, where we were working with a 2D list with ice cream data.
# Assume data is a 2D list parsed from the file
for row in range(len(data)):
    data[row].pop(0) # remove the ID
    chocCount = 0 # count number of chocolate
    for col in range(len(data[row])):
        # Make all flavors lowercase
        data[row][col] = data[row][col].lower()
        if "chocolate" in data[row][col]:
            chocCount += 1
    # track chocolate count
    data[row].append(chocCount)
print(data)
Using the code above as an example, write your own code to find the number of times strawberry ice cream appeared in the dataset.
[23.16]
The code below is from lecture, where we were working with a 2D list with ice cream data.
# Assume data is a 2D list parsed from the file
for row in range(len(data)):
    data[row].pop(0) # remove the ID
    chocCount = 0 # count number of chocolate
    for col in range(len(data[row])):
        # Make all flavors lowercase
        data[row][col] = data[row][col].lower()
        if "chocolate" in data[row][col]:
            chocCount += 1
    # track chocolate count
    data[row].append(chocCount)
print(data)
Using the code above as an example, write your own code to find the number of times vanilla ice cream or matcha ice cream appeared in the dataset. Note: this involves searching for multiple words.